Up to four models
Claude Haiku 5.5 vs GLM-5.3
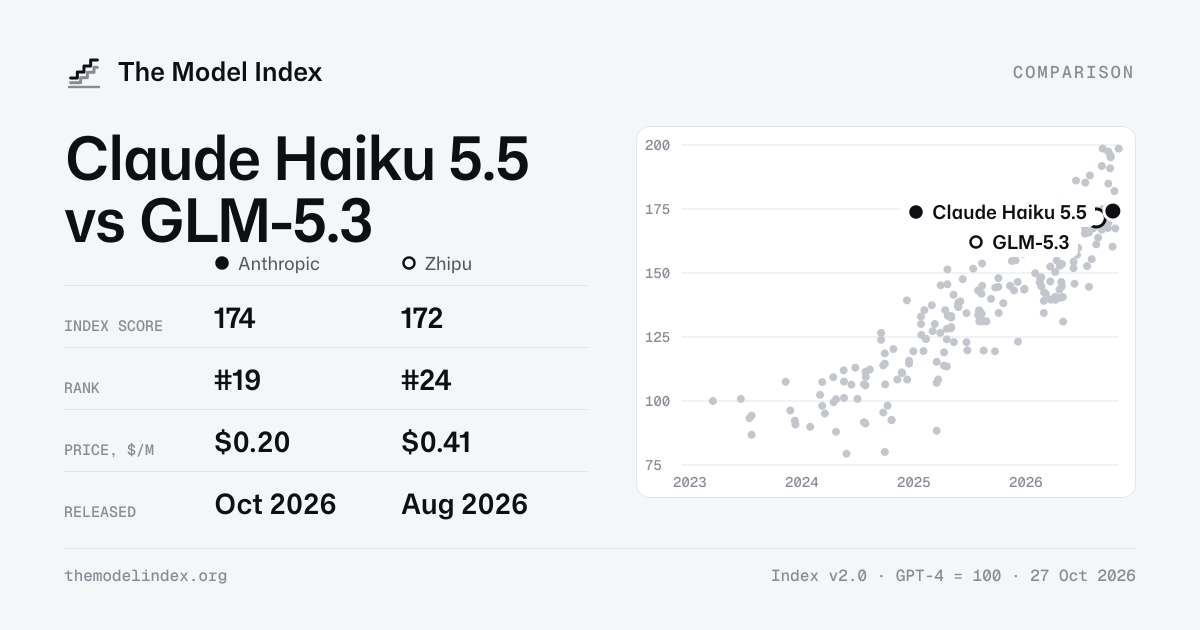
On the index (GPT-4 = 100), Claude Haiku 5.5 scores 174 and GLM-5.3 172. Side by side on the same third-party tests, with price and context. The link in your address bar shares this exact comparison.
Claude Haiku 5.5
174158–191
WeightsClosed
ReleasedOct 2026
Price in / out$0.10 / $0.50
Context1M
Core tests taken7 of 9
 GLM-5.3
172155–188
WeightsOpen
ReleasedAug 2026
Price in / out$0.077 / $1.4
Context1.05M
Core tests taken5 of 9
Claude Haiku 5.5 and GLM-5.3 are too close to call (3 points apart, within the uncertainty), ahead on 1 of 5 shared core tests, and costs 2.0× less.
Test by testthird-party results
Claude Haiku 5.5GLM-5.3
GLM-5.3Every result as a table
| Test | Claude Haiku 5.5 | GLM-5.3 |
|---|---|---|
| Reasoning & knowledge | ||
| GPQA Diamond (Epoch AI) | 89.6% | 90.9% |
| LiveBench Data Analysis | 72.8% | 70.2% |
| LiveBench IF | 66.5% | 69.3% |
| LiveBench Language | 63.5% | 79.9% |
| LiveBench Reasoning | 84.6% | 85.8% |
| SimpleQA Verified | 23.8% | 41.0% |
| Maths | ||
| FrontierMath (tiers 1-3) | 75.1% | 68.8% |
| AIME-style maths (OTIS mock) | 98.9% | 91.1% |
| LiveBench Mathematics | 92.8% | 87.9% |
| ProofBench v1.1 | 89.0% | 49.0% |
| Chess puzzles | 55.0% | 37.0% |
| FrontierMath (tier 4) | 46.3% | 29.3% |
| Coding | ||
| Terminal-Bench 4.0 | 36.4% | 38.9% |
| LiveBench Agentic Coding | 57.2% | 60.9% |
| LiveBench Coding | 77.9% | 79.0% |
| Code Migration | 44.6% | 44.2% |
| CyberBench v1.1 | 75.5% | 72.1% |
| IOI | 47.3% | 68.4% |
| ProgramBench | 2.5% | 1.5% |
| Vibe Code Bench 1-100 | 20.4% | 20.0% |
| Vibe Code Bench v1.1 | 90.4% | 78.1% |
| FrontierSWE | 43.8% | 30.2% |
| Agents | ||
| APEX-Agents | 56.1% | 56.6% |
| SRE Bench | 5.7% | 9.2% |
| Terminal-Bench-Science | 10.0% | 5.7% |
| DTBench | 95.0% | 87.7% |
| LMCA | 51.1% | 55.5% |
| Mystery game puzzles | 30.0% | 33.0% |
| Professional work | ||
| Finance Agent (v2) | 54.1% | 55.8% |
| EMB | 59.0% | 56.3% |
| HLAB-Vals-1.1 | 4.2% | 14.6% |
| Legal Research Bench | 43.8% | 49.0% |
| MedCode | 51.5% | 42.9% |
| MedScribe | 89.5% | 88.8% |
| Public Benefits Bench v1.1 | 63.2% | 68.5% |
| Tax Agent Bench | 31.9% | 39.7% |
| Novel problems | ||
| MysteryMechanism | 35.1% | 23.0% |
Tests at least two of these models have taken. Bold rows are the core tests.