Up to four models
GPT-5.1 vs GPT-5
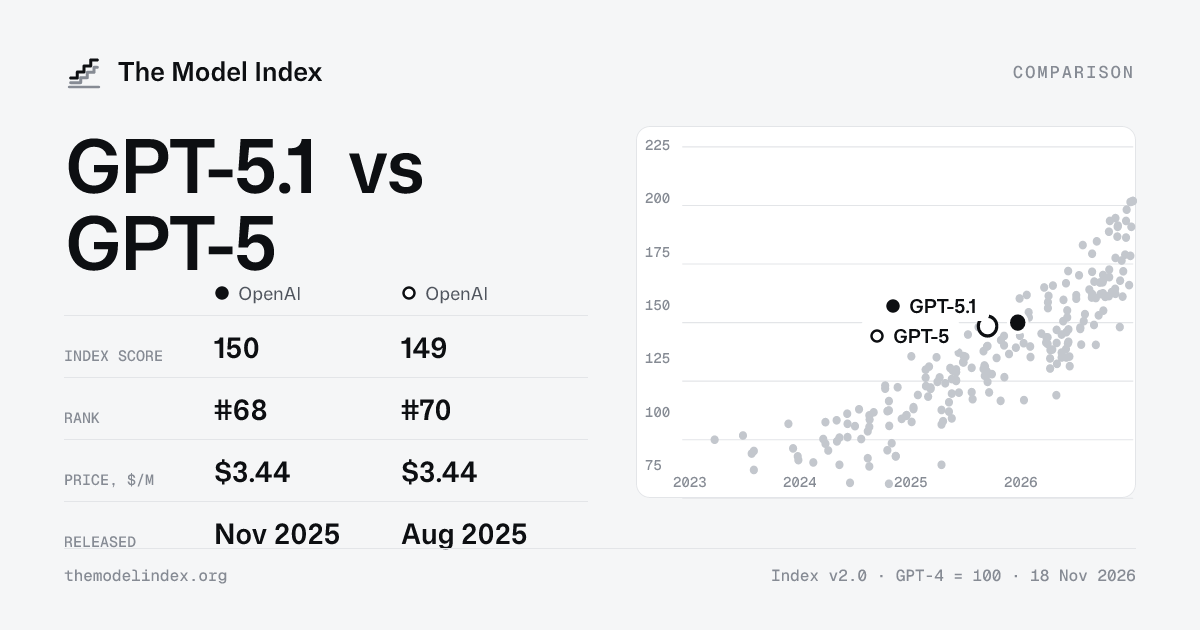
On the index (GPT-4 = 100), GPT-5.1 scores 150 and GPT-5 149. Side by side on the same third-party tests, with price and context. The link in your address bar shares this exact comparison.
GPT-5.1
150134–166
WeightsClosed
ReleasedNov 2025
Price in / out$1.25 / $10
Context400K
Core tests taken4 of 9
GPT-5
149133–164
WeightsClosed
ReleasedAug 2025
Price in / out$1.25 / $10
Context400K
Core tests taken6 of 9
GPT-5.1 and GPT-5 are too close to call (2 points apart, within the uncertainty), ahead on 2 of 4 shared core tests, at a similar price.
Test by testthird-party results
GPT-5.1GPT-5
Every result as a table
| Test | GPT-5.1 | GPT-5 |
|---|---|---|
| Reasoning & knowledge | ||
| GPQA Diamond (Epoch AI) | 87.6% | 86.2% |
| Humanity's Last Exam | 23.7% | 25.3% |
| GPQA Diamond (Vals AI) | 86.6% | 85.6% |
| MMLU Pro | 86.4% | 86.5% |
| MMMU Pro | 83.2% | 81.5% |
| SimpleBench | 53.2% | 56.7% |
| SimpleQA Verified | 48.0% | 50.1% |
| VPCT | 58.7% | 66.0% |
| Maths | ||
| AIME-style maths (OTIS mock) | 88.6% | 91.4% |
| MGSM | 93.0% | 92.8% |
| Chess puzzles | 42.0% | 36.0% |
| FrontierMath (2025 set) | 31.0% | 32.4% |
| FrontierMath tier 4 (2025 set) | 12.5% | 12.5% |
| Coding | ||
| SWE-bench Verified | 68.0% | 73.6% |
| Terminal-Bench 2.0 (Terminus 2 runs) | 47.6% | 35.2% |
| LiveCodeBench | 86.5% | 85.9% |
| SWE-bench | 69.8% | 69.0% |
| Vibe Code Bench v1.1 | 24.6% | 20.1% |
| GSO-Bench | 13.7% | 6.9% |
| WeirdML | 60.8% | 60.7% |
| Agents | ||
| DTBench | 90.1% | 90.7% |
| DeepResearch Bench | 42.8% | 49.6% |
| LMCA | 43.9% | 40.0% |
| Mystery game puzzles | 19.0% | 23.0% |
| Professional work | ||
| CorpFin v2 | 63.8% | 61.1% |
| LegalBench | 85.7% | 86.0% |
| MedCode | 52.7% | 49.6% |
| MedScribe | 88.1% | 83.7% |
| MortgageTax | 61.4% | 65.5% |
| TaxEval v2 | 74.9% | 73.4% |
| Novel problems | ||
| ARC-AGI-2 | 17.6% | 9.9% |
| ARC-AGI-1 | 72.8% | 65.7% |
Task length · METR42 sec
Tests at least two of these models have taken. Bold rows are the core tests.