Up to four models
o3 vs Grok 4.3 Beta
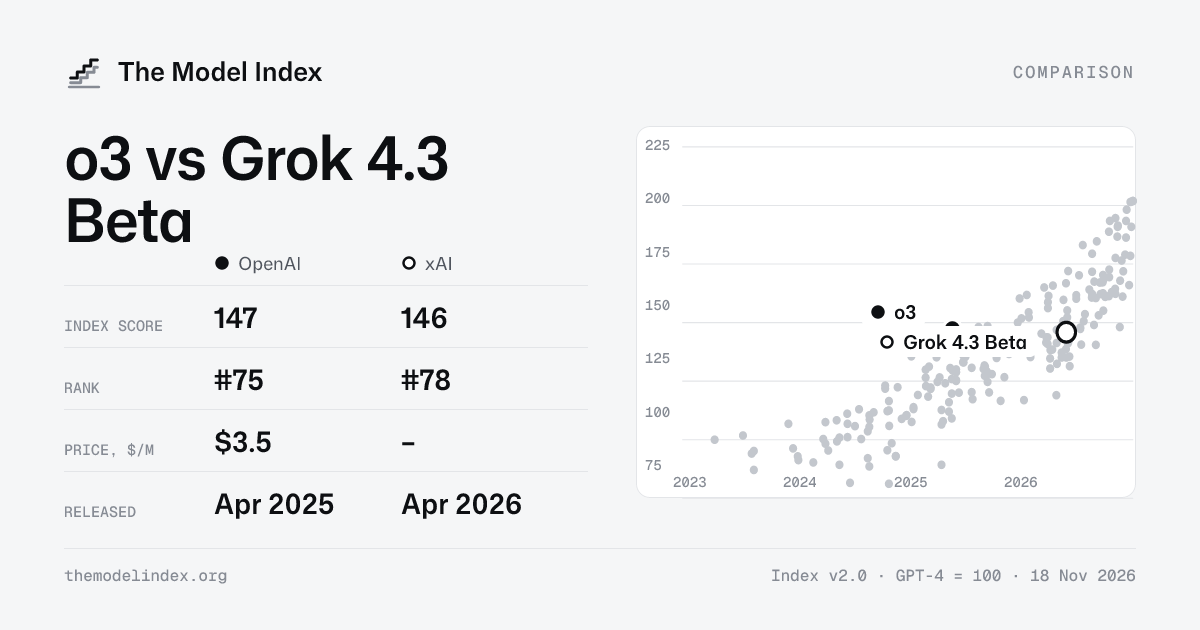
On the index (GPT-4 = 100), o3 scores 147 and Grok 4.3 Beta 146. Side by side on the same third-party tests, with price and context. The link in your address bar shares this exact comparison.
o3 and Grok 4.3 Beta are too close to call (1 point apart, within the uncertainty), ahead on 0 of 2 shared core tests.
Test by testthird-party results
o3Grok 4.3 Beta
Every result as a table
| Test | o3 | Grok 4.3 Beta |
|---|---|---|
| Reasoning & knowledge | ||
| GPQA Diamond (Epoch AI) | 81.8% | 88.8% |
| GeoBench | 74.0% | 56.0% |
| SimpleQA Verified | 49.4% | 33.2% |
| Maths | ||
| FrontierMath (tiers 1-3) | 33.3% | 42.8% |
| AIME-style maths (OTIS mock) | 84.4% | 93.3% |
| Chess puzzles | 37.0% | 18.0% |
| Coding | ||
| WeirdML | 52.4% | 49.9% |
| Agents | ||
| DTBench | 84.8% | 90.7% |
| LMCA | 39.7% | 38.3% |
Task length · METR39 sec
Tests at least two of these models have taken. Bold rows are the core tests.