Up to four models
Qwen3.8-27B vs Kimi K2.7 Code
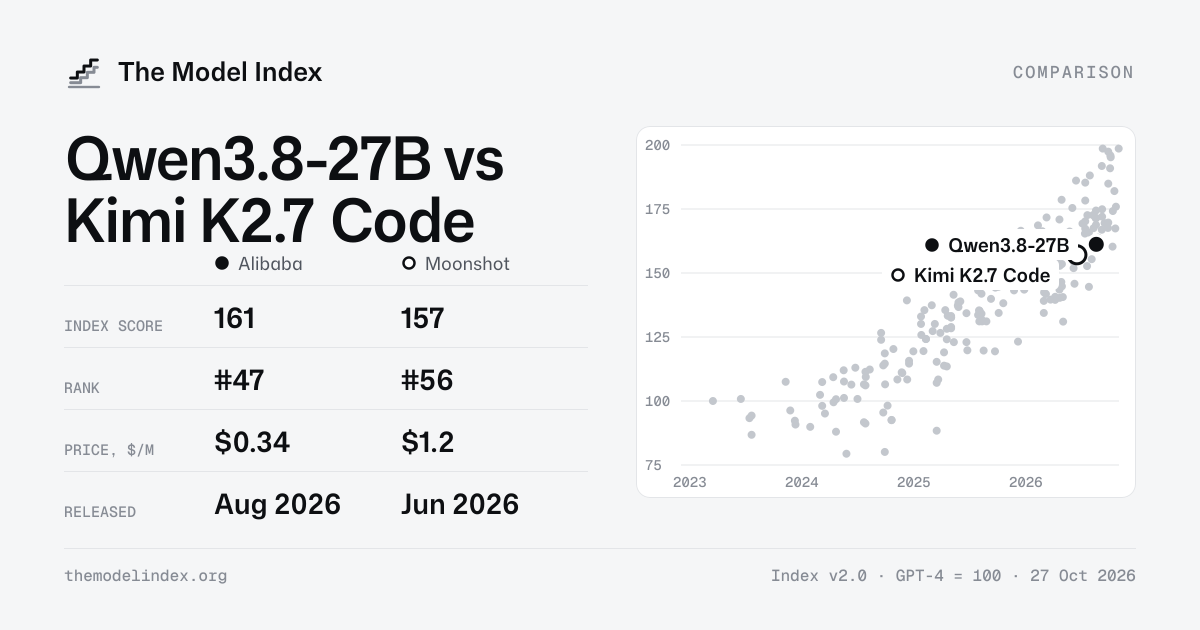
On the index (GPT-4 = 100), Qwen3.8-27B scores 161 and Kimi K2.7 Code 157. Side by side on the same third-party tests, with price and context. The link in your address bar shares this exact comparison.
 Qwen3.8-27B
161145–178
WeightsOpen
ReleasedAug 2026
Price in / out$0.039 / $1.25
Context1M
Core tests taken3 of 9
Kimi K2.7 Code
157141–174
WeightsOpen
ReleasedJun 2026
Price in / out$0.56 / $3.1
Context262K
Core tests taken3 of 9
Qwen3.8-27B leads Kimi K2.7 Code by 4 points, ahead on 1 of 1 shared core tests, and costs 3.5× less.
Test by testthird-party results
Qwen3.8-27BKimi K2.7 CodeEvery result as a table
| Test | Qwen3.8-27B | Kimi K2.7 Code |
|---|---|---|
| Reasoning & knowledge | ||
| LiveBench Data Analysis | 76.6% | 62.7% |
| LiveBench IF | 72.7% | 56.3% |
| LiveBench Language | 74.4% | 77.9% |
| LiveBench Reasoning | 80.0% | 82.8% |
| Maths | ||
| LiveBench Mathematics | 86.2% | 79.6% |
| Surface Evolver Bench | 45.0% | 48.8% |
| Coding | ||
| LiveBench Agentic Coding | 61.4% | 45.7% |
| LiveBench Coding | 75.7% | 74.0% |
| Code Migration | 14.2% | 25.4% |
| LiveCodeBench | 84.0% | 82.0% |
| ProgramBench | 0.0% | 0.0% |
| SWE-bench | 86.0% | 78.2% |
| Vibe Code Bench v1.1 | 64.8% | 47.2% |
| Agents | ||
| APEX-Agents | 47.5% | 37.6% |
| SkillsBench | 38.1% | 50.0% |
Tests at least two of these models have taken. Bold rows are the core tests.