Up to four models
Llama 3.2 11B vs Mistral 7B v0.3
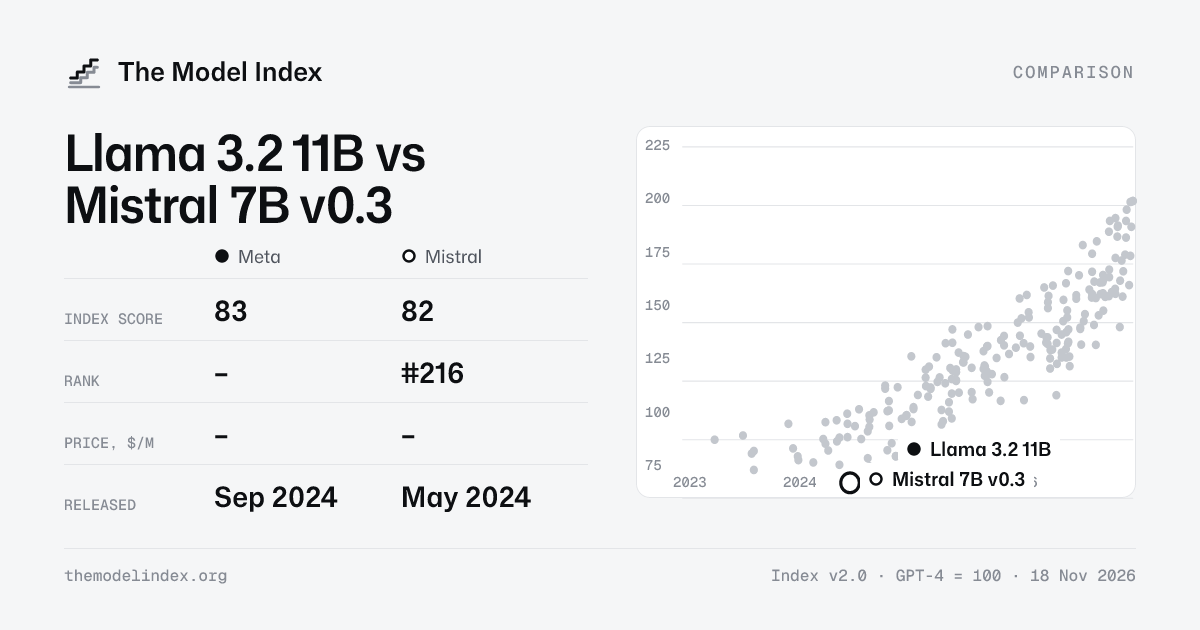
On the index (GPT-4 = 100), Llama 3.2 11B scores 83 and Mistral 7B v0.3 82. Side by side on the same third-party tests, with price and context. The link in your address bar shares this exact comparison.
Llama 3.2 11B and Mistral 7B v0.3 are too close to call (2 points apart, within the uncertainty).
Test by testthird-party results
 Llama 3.2 11B
 Mistral 7B v0.3
Every result as a table
| Test | Llama 3.2 11B | Mistral 7B v0.3 |
|---|---|---|
| Reasoning & knowledge | ||
| MMLU (HELM runs) | 56.5% | 59.9% |
Tests at least two of these models have taken. Bold rows are the core tests.