Grok Build 0.1
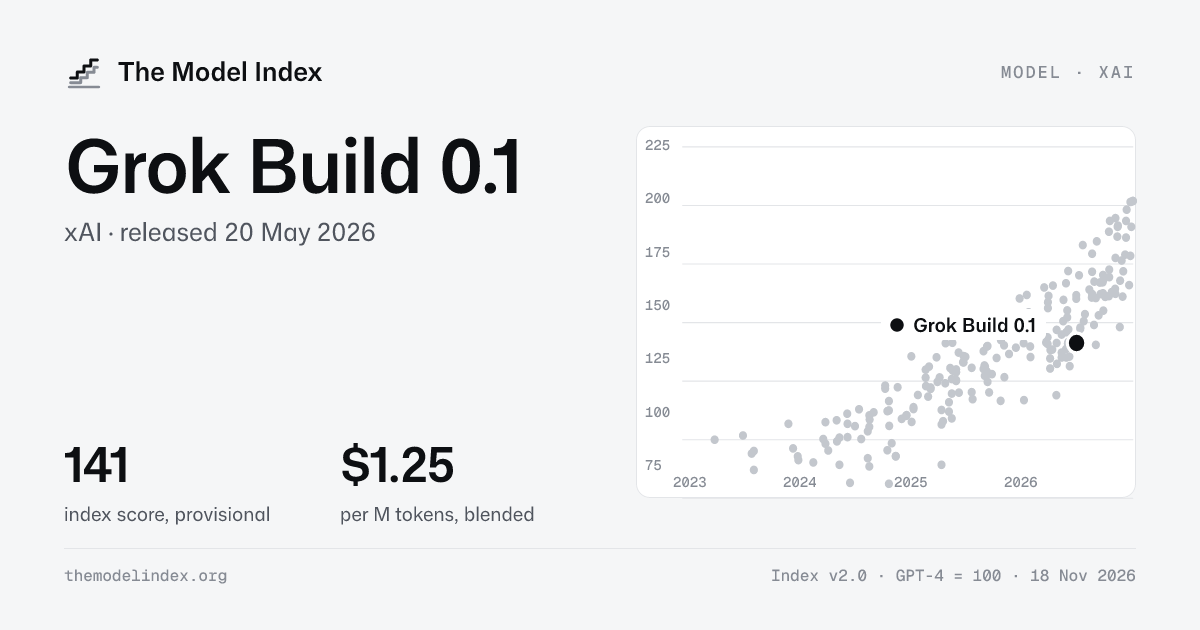
Grok Build 0.1 is a closed AI model from xAI with an index score of 141 (GPT-4 = 100), provisional.
141114–169Index scoreProvisional · one third-party tester so far; ranked once a second confirms it
$1.0/ $2.0Price per million tokensinput / output · via OpenRouter
256KContext windowtokens it reads at once
20 May 2026Released6 months ago
Where it sitson the frontier
o3 reached this score 13 months earlier.
Test resultsby area · tick = best by any model
Reasoning & knowledgeevidence
Mathsevidence
Codingevidence
Agentsno evidence yet
Professional workno evidence yet
Novel problemsno evidence yet
Long tasksno evidence yet
Third-party results only, at the model’s best standard setting. Hover a bar for who ran it.
What others sayrank on each leaderboard
Not on any of the rankings we follow yet.
Best attop three among current models
Not in the top three among current models on any category we track.
Where to use itprices checked 18 Nov 2026
API providers 1 · per 1M tokens, in / out
Host prices from OpenRouter; going direct can differ.
Facts and sources
Released20 May 2026
Announcementx.ai ↗
Release entryGrok Build 0.1 (coding)
Scored asGrok Build 0.1
Output speed–
Hugging Faceclosed weights